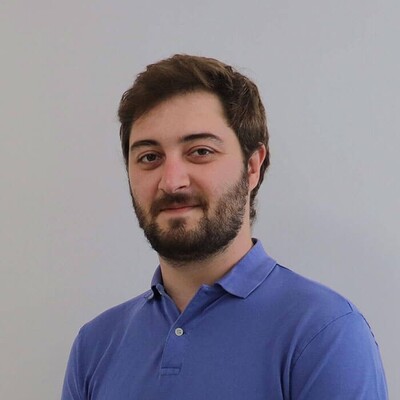
Stan Girard is the founder of Quivr , an open-source RAG framework with 38K+ GitHub stars. Based in Paris, he runs GenAI at Theodo while building tools that let developers integrate document search into their applications. His side project went viral in May 2023 after he built the first version in a single afternoon.
Background
- Engineering degree from EPITA (French computer science school)
- Head of GenAI at Theodo
- Site Reliability Engineer background with AWS, Azure, Kubernetes
- Y Combinator W24 batch with co-founder Antoine Dewez
- Built the initial Quivr prototype in one afternoon, tweeted it, went viral
GitHub | Twitter | LinkedIn | Blog
The Quivr Approach
Quivr started as a personal project: dump all your documents into a vector store and query them with GPT-4. The original pitch was “your second brain.”
The framework has since evolved into an opinionated RAG toolkit for developers:
from quivr_core import Brain

brain = Brain.from_files(
    name="my-brain",
    file_paths=["./docs/report.pdf", "./docs/notes.md"]
)

answer = brain.ask("What were the key findings?")
print(answer.answer)
Five lines to go from files to conversational search.
Architecture
Quivr uses a node-based workflow system. A basic RAG pipeline looks like this:
workflow_config:
  name: "standard-rag"
  nodes:
    - name: "filter_history"
      edges: ["rewrite"]
    - name: "rewrite"
      edges: ["retrieve"]
    - name: "retrieve"
      edges: ["generate_rag"]
    - name: "generate_rag"
      edges: []
| Node | Purpose |
|---|---|
| filter_history | Trim conversation context to fit token limits |
| rewrite | Transform user query for better retrieval |
| retrieve | Vector search against document embeddings |
| generate_rag | LLM generates answer from retrieved chunks |
You can swap nodes, add reranking, or insert custom processing steps.
MegaParse: The Document Problem
RAG systems live or die by parsing quality. Girard built MegaParse (7K stars) to handle the messiest part of the pipeline.
The core insight: different documents need different strategies.
OCR vs direct extraction:
- If a PDF page is more than 50% images, use OCR
- Otherwise, use pdfminer for fast text extraction
Table handling:
- Use LLMs to reconstruct tables from draft extractions
- Use vision models for complex table layouts
from megaparse import MegaParse

parser = MegaParse()
result = parser.parse("quarterly-report.pdf")
# Handles tables, images, mixed layouts
This modular approach means you can tune parsing for your specific document types.
Model Flexibility
Quivr supports any LLM provider:
from quivr_core import LLMEndpoint
from langchain_openai import ChatOpenAI
from langchain_anthropic import ChatAnthropic

# OpenAI
openai_llm = LLMEndpoint(llm=ChatOpenAI(model="gpt-4o"))

# Anthropic
claude_llm = LLMEndpoint(llm=ChatAnthropic(model="claude-sonnet-4-20250514"))

# Local with Ollama
from langchain_community.chat_models import ChatOllama
local_llm = LLMEndpoint(llm=ChatOllama(model="llama3.2:8b"))
Run fully local with Ollama, or use cloud APIs. The abstraction stays the same.
From Second Brain to Enterprise
The project has shifted focus since Y Combinator. Quivr now targets customer support automation, using the same RAG infrastructure for a different use case.
From the Quivr newsletter :
“We tried to support every LLM provider simultaneously. It made the backend complicated and the UX worse. So we built Genoss as a separate abstraction layer. Now Quivr is a simple application with streaming that’s actually nice to use.”
The lesson: solve complexity by splitting it out, not by adding more options.
Open Source Strategy
Girard’s take on building in public:
- Open source without marketing stays a hobby project
- The code is table stakes; distribution matters more
- Sponsors and backers (Theodo, Aleios, Padok, Sicara) provide runway
- 65th most-starred AI project on GitHub within 6 months
| Metric | Value |
|---|---|
| GitHub stars | 38.9K |
| Contributors | 123 |
| Releases | 354 |
| License | Apache 2.0 |
Practical RAG Patterns
From Quivr’s documentation, patterns that work:
Chunk size matters:
- Too small: lose context
- Too large: dilute relevance
- Default: 500 tokens with 100 token overlap
Reranking improves quality:
reranker_config:
  supplier: "cohere"
  model: "rerank-multilingual-v3.0"
  top_n: 5
Conversation history window:
- Default: 10 turns
- Trim aggressively to stay within token limits
Key Takeaways
| Principle | Implementation |
|---|---|
| Start with a working demo | Built v1 in one afternoon, iterated from there |
| Parsing quality determines RAG quality | MegaParse handles documents, tables, images |
| Abstraction over configuration | YAML workflows, any LLM provider |
| Solve complexity by splitting | Genoss handles LLM abstraction separately |
| Open source needs distribution | Marketing matters as much as code |